Command Palette

Search for a command to run.

GitHub stars
FIG_001

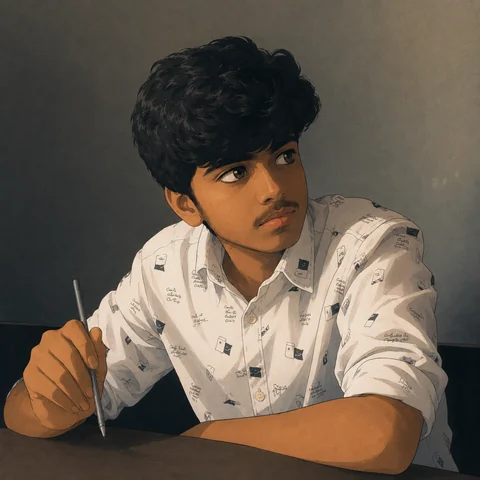
Yugesh Sappidi

AI Engineer

Overview

Graduate Research Assistant @UI Health

Social Links

Hello

I'm an AI Engineer focused on LLM safety, evaluation, and inference. I completed my MS in Computer Science at UIC in May 2026. I care about what makes a model ready for real users: reliability, cost, and answers grounded in evidence.

At UI Health, I built a clinical RAG system over patient records that answers over WhatsApp at 1.2s median latency, with a 60% reduction in response failures. My projects explore the same questions through medical LLM red teaming with MediCS, shared memory for coding agents with Mnemo, and adaptive inference with AdaTTT.

I build with strong baselines, confidence intervals, and ablations, and I document the results even when they challenge my approach. Red teaming taught me to trust a system only after a serious attempt to break it.

GitHub Contributions

Experience

  • Designed RAG pipelines over clinical datasets, enabling natural-language querying of both structured and unstructured patient records for faster clinical insights.
  • Built a FastAPI + GPT-4 + Pinecone retrieval backend with chunked embeddings, grounding LLM outputs in source clinical documents to reduce hallucination.
  • Optimized the retrieval pipeline for low-connectivity environments, reaching 1.2s median latency under constrained network conditions.
  • Integrated Twilio for reliable concurrent WhatsApp sessions, managing conversation state with Cloudflare D1 and KV Store to keep interactions consistent at scale.
  • Containerized the full pipeline with Docker and orchestrated it on Kubernetes (Helm), cutting response failures by 60% through better fault isolation.
  • RAG
  • LLMs
  • Clinical NLP
  • FastAPI
  • GPT-4
  • Pinecone
  • Vector Retrieval
  • Twilio
  • Cloudflare D1 / KV
  • Docker
  • Kubernetes
  • Helm
  • React.js
  • Redux
  • JavaScript
  • React Hooks
  • Docker
  • Docker Compose
  • Figma
  • Mocha

Projects[7]

  • Claude Code and Codex forget everything between sessions, and neither knows what the other learned. Mnemo is one local memory both use over MCP, scoped to your repository, with every change attributed to an agent and reversible.

    • Where it started. A write-time quality gate: extract facts from conversations, then verify, dedupe and score each one before storing it, because agent memory fills up with junk. On an 18-turn scripted test, precision rose from 60% to 90.9%.
    • Real conversations did not hold up. Over eleven cycles with frozen protocols, small local extractors scored 1.41% strict precision on a 200-turn conversation. I wrote up each failure instead of tuning around it, and changed direction.
    • The pivot. A coding agent already knows what mattered in its own session, so I parked extraction and let the agent decide what to save through six guarded MCP tools. History and undo exist elsewhere, so I competed on guarantees.
    • Guarantees in the database. Postgres triggers reject edits to past events, updates must name the revision they read, and each change commits with an idempotency receipt, so stale writes fail and retries never apply twice.
    • Shared, with attribution. At first Codex could not see what Claude Code saved, because reads were filtered by agent ID. Now each agent writes under its own name, into a project scope keyed by the git remote plus a global scope.
    • Measured with the real agents. Ten scenarios drive 23 real Claude Code and Codex sessions. The baseline passed 4 of 10 because Codex never saved anything it was told. A short memory policy in its instructions took both agents to 10 of 10.
    • Installable by someone else. uv tool install, then mnemo up and mnemo install. The installer checks dependencies, shows every config change before making it and uninstalls cleanly. Nothing leaves the machine. 450+ tests.
    • What's next. Harder evals on real repositories and long sessions, with repeated runs reported as rates rather than single passes. Then more of the git layer: grouped undo, undoing a creation, and branching and merging memory.
    • Python
    • Postgres + pgvector
    • MCP Server
    • Event Sourcing
    • Claude Code + Codex
    • Agent Evaluation
  • A closed-loop red-teaming and defense framework for medical LLMs, built around one uncomfortable finding: safety alignment holds in English and leaks badly the moment a prompt switches languages mid-sentence.

    • The attack. An agentic red team runs 5 strategies across 6 low-resource languages and 6 harm categories. A Thompson-Sampling bandit per category learns which strategy actually lands, instead of firing a fixed battery of templates and reporting the total.
    • What it exposed. 27.6% attack success rate on Llama-3-8B-Instruct. The attacks then transfer upward to models they were never tuned against: 61.7% on Mistral-7B, 51.6% on Qwen-2.5-7B.
    • The defense. One round of QLoRA supervised fine-tuning on red-team output cuts ASR to 6.4% (−21.2 pp, p < 0.0001, paired bootstrap 95% CI [−23.5, −18.9]). Helpfulness retention goes up to 99.6% and false refusals drop to 0.4%, so the model did not just learn to refuse everything.
    • The negative result I shipped anyway. Stacking DPO on the SFT checkpoint regressed safety back to 21.5%. DPO's whole premise is correcting over-refusal caused by safety training. When there is no over-refusal to correct, it eats the safety margin instead. I wrote that up rather than quietly dropping the run.
    • MediCS-500. 500 expert-curated harmful seeds plus 500 benign twins, code-switched into 6 languages with back-translation verification, so jailbreak susceptibility and over-refusal are measured on the same benchmark.
    • Evaluation. 3 checkpoints × 3 seeds × 1,599 held-out attacks, judged by GPT-5 at temperature 0. McNemar with Holm-Bonferroni across languages, Cohen's h, residual-failure breakdown, cross-architecture transfer, and a fairness audit that treats language as the protected attribute. 213 tests.
    • PyTorch
    • Llama 3 / QLoRA
    • TRL (SFT + DPO)
    • PEFT
    • Red Teaming
    • Statistical Evaluation

Education

Certifications[3]

Bookmarks[13]

After hours[4]

Listening
Tuning in

A moment of quiet

Checking Spotify…

Spotify
Moving
Checking

A little every day

Move
–
Exercise
–
Stand
–
Checking activity…
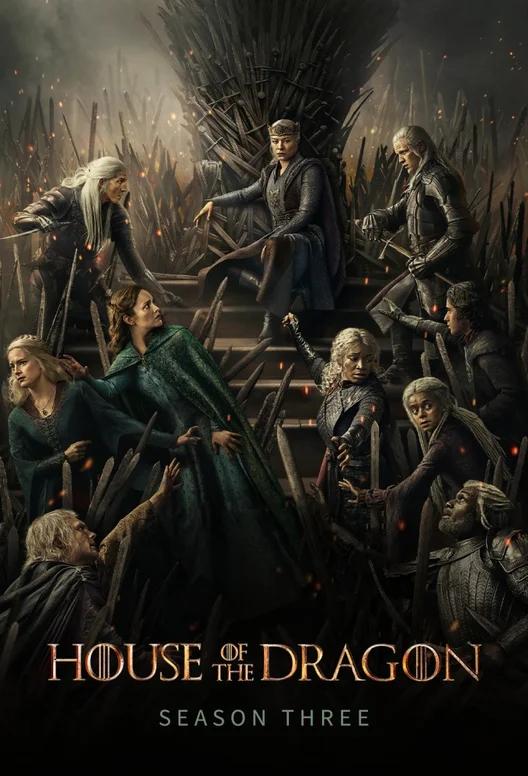
Credits rolled
House of the Dragon Season 3 ensemble poster: Rhaenyra and the cast gathered around the Iron Throne

Admit oneSeason 3

House of the Dragon
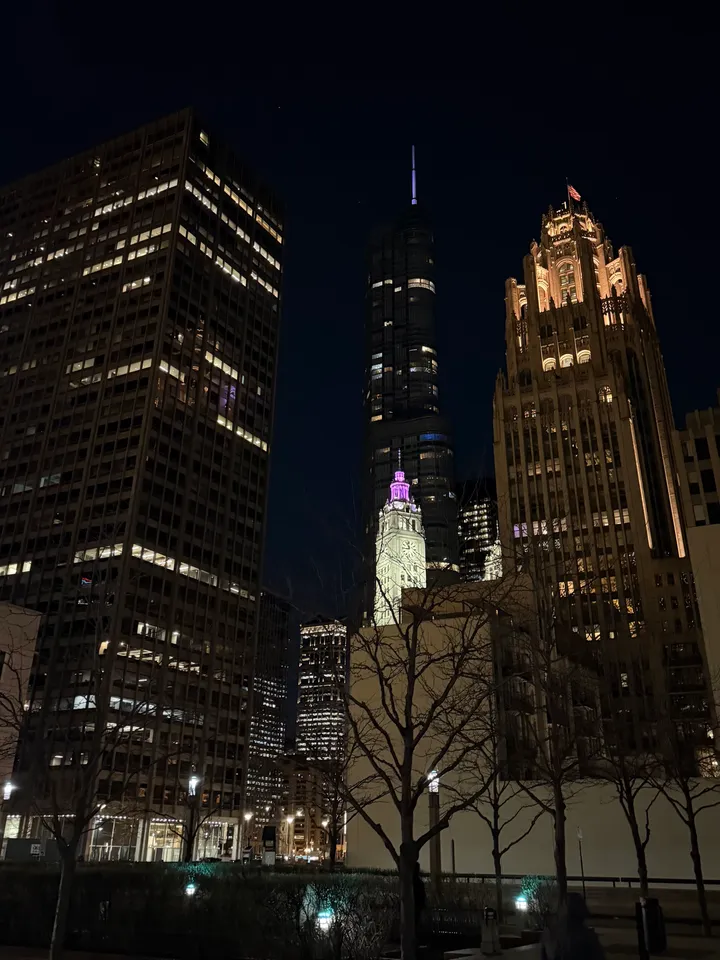
Last stop
Chicago skyline at night from North Michigan Avenue: the floodlit Gothic crown of Tribune Tower beside the Wrigley Building clock tower and Trump Tower
Tribune Tower24mm ƒ/1.78 1/30s ISO 1600
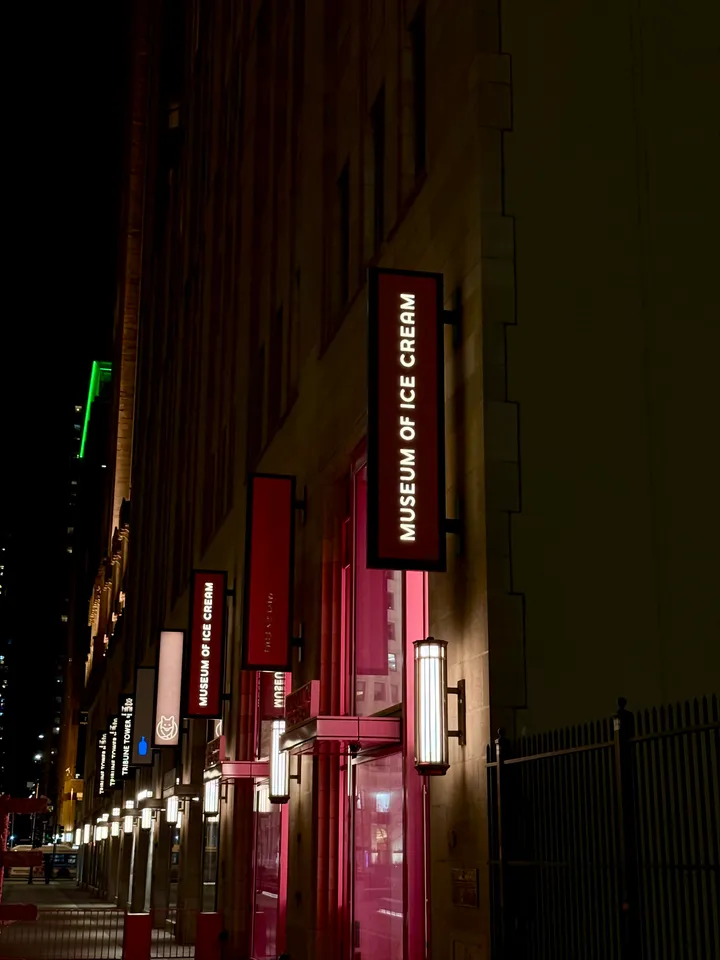
Lit Museum of Ice Cream banners hanging along the stone facade of Tribune Tower at night
Museum of Ice Cream48mm ƒ/1.78 1/40s ISO 200

About this site

Deployed on
Vercel
Source code
GitHub
Typeface
GeistSans & Mono
Stack
next@16.2.6react@19.2.6tailwindcss@4.3.0

Inspired by

  1. Chanh Dai
  2. Emil Kowalski
  3. Rauno Freiberg
  4. shadcn/ui

Command Palette

Search for a command to run.